Fastest AI Inference at Any Scale
Build and run AI with more performance, better economics, and full control over where it runs.
Powered by
Instinct™
3.43x
Higher inference
15x
Lower latency
Connecting to model...
Trusted by our partners


Built For Speed, Proven in Production
Engineered from the runtime up for lower latency, higher throughput, and consistent performance at scale.
Playground
0.00s
0 tok/s
Qwen3.6-35B
81.33k tok/s
Running at 8× MI350X
Qwen3.6-35B
11,161k tok/s
Running at 1× MI350X
Qwen3.6-27B
6,500.89 tok/s
Running at 1× MI350X
Read the Qwen3.6 benchmark
—
Total tokens processed to date
Bring Your AI Stack To Production
Run your AI
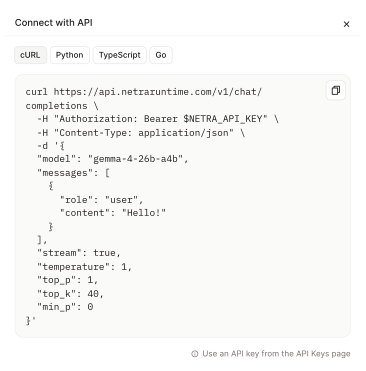
Serve open models on managed GPUs in minutes with a simple OpenAI-compatible API.
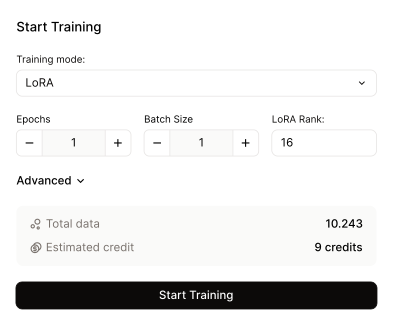
Train on your data
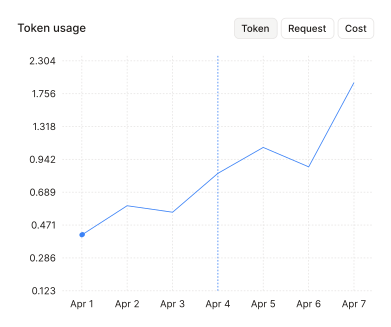
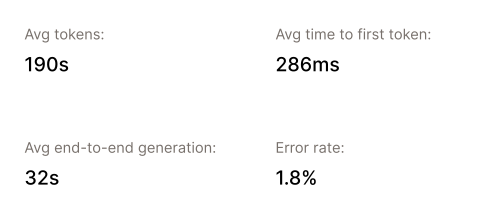
Monitor everything
Deploy to production
One AI Platform, Choose Where It Runs
Exclusive Licensing Partner
You Got Questions? We Got Answers
What is Netra Runtime?
Netra Runtime is a high-performance AI inference engine that helps you run AI models faster and get more output from the same GPUs. It sits between your AI application and GPU infrastructure, optimizing how models run in production.
Why should I use Netra Runtime?
How much faster is Netra Runtime?
Can Netra Runtime run on my own infrastructure?
What is GSC’s role at Netra Runtime?
Which GPUs does Netra Runtime support?
Is Netra Runtime suitable for private AI?
What is Netra Cloud?
How do I get started with Netra?
Build, share, and learn together
Connect with developers building and deploying AI with Netra.