Netra Runtime Blog
August 22, 2026
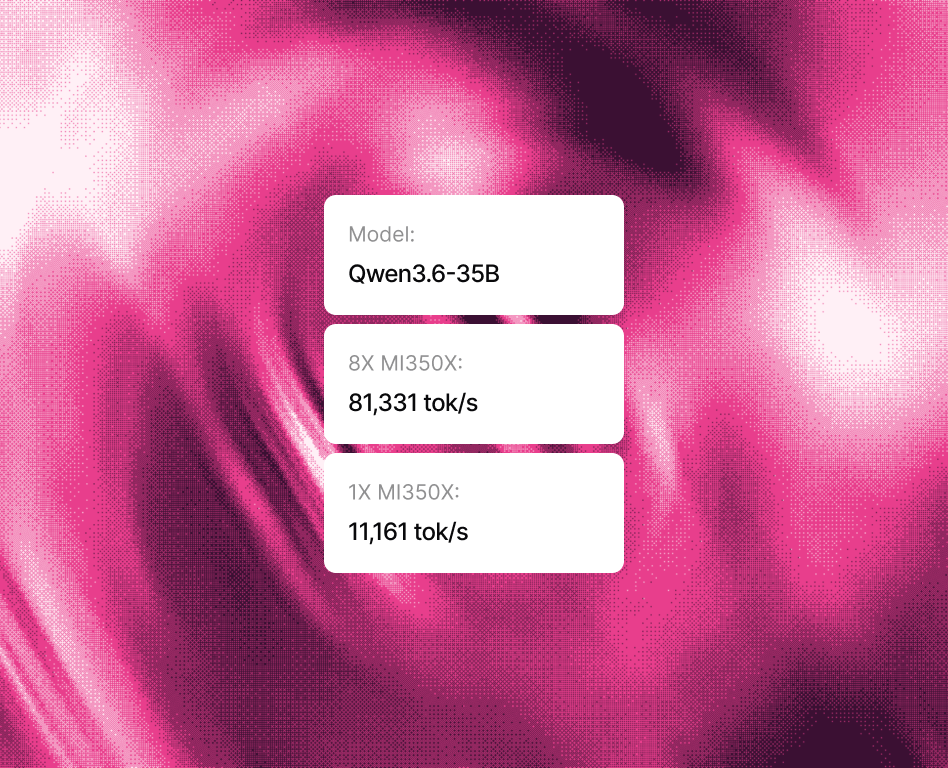
Netra Kernel: Open-Source ROCm Kernels for AMD MI350X
Read Article
Latest articles
Customer Support Replies with DeepSeek V4 Flash on Netra
September 29, 2026
Up to 4x Faster Than vLLM
June 24, 2026
One Blocking Memcpy Per Verify Step
July 23, 2026
Three Layers of a Burst-Admission Stall
July 23, 2026
Kernel Surgery on a Production Qwen Deployment
July 23, 2026
Fusing RMSNorm and FP8 Quantization Under torch.compile
July 22, 2026
Radix Islands: How Eager SWA Eviction Doubled Our Serving Concurrency
July 22, 2026
H100s at $0.74 an hour: bidding blind in GPU spot auctions
July 19, 2026
Sovereign AI in Southeast Asia: What It Means and Why It Matters
July 15, 2026
vLLM Paged Attention and Continuous Batching Explained
July 14, 2026
How to Speed Up GDN Kernels for Qwen Models
July 14, 2026
How Much VRAM Do You Need to Run an LLM?
July 14, 2026
How to Count Tokens (and Why It Affects Your Bill)
July 11, 2026
Cara Memilih Tool OCR Bahasa Indonesia untuk Pipeline AI
July 10, 2026
The Best Free OCR Tools for Documents & AI Pipelines
July 8, 2026
Token Counter: Estimate Tokens Before You Send a Prompt
July 6, 2026